


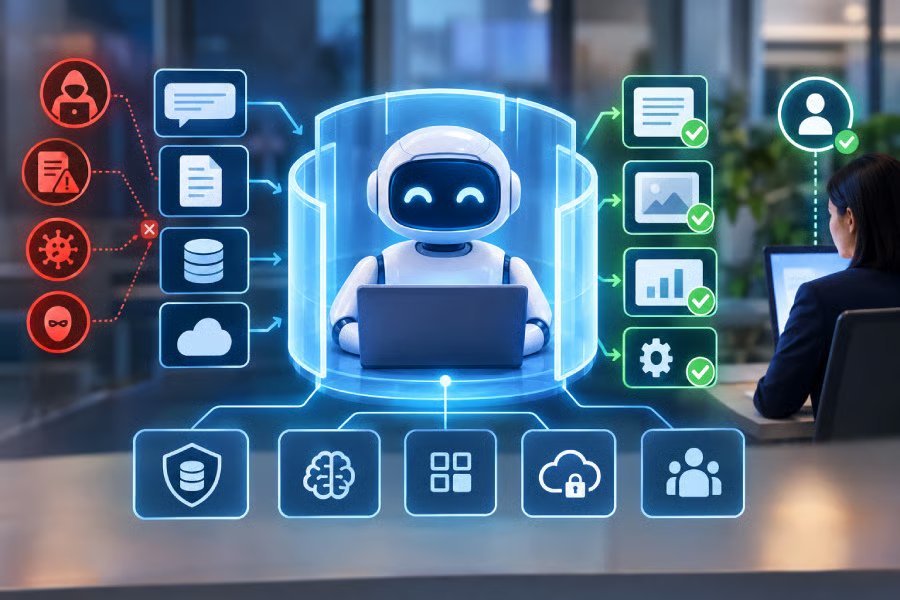
AI guardrails help organizations limit what AI systems can access, generate, and change.
These controls become especially important as enterprise AI evolves from generating text into autonomous agents capable of modifying customer databases, calling tools, and initiating transactions. Mistakes can affect live business systems rather than simply produce an inaccurate answer.
For IT teams, the practical challenge is deciding where to enforce permissions, which actions require approval, and how to detect and stop failures.
Salesforce argues that agentic AI, which can call tools, update records and send messages without a human checking each step, changes the question from “did it say the right thing?” to “did it do the right thing?” A bad output is no longer a clumsy sentence; it is an unauthorized financial transfer or a leaked sensitive record. Guardrails can reduce these risks, but their effectiveness depends on how they are implemented, tested, and monitored.
Here is an in-depth breakdown of what they are, how they operate across systems, and why they determine the boundary between enterprise automation and corporate liability.
- Defining the guardrail: Why a prompt is not a control
- The four architectural layers
- Data layer
- Model layer
- Application layer
- Infrastructure layer
- Anatomy of an execution: The five-stage operational loop
- The rising stakes: Agents, tool hijacking, and emergent exploits
- The strategic cost of getting guardrails wrong
- Why agent permissions matter
- Business, technology, and consumer realities
- Blueprint for decision-makers: Evaluating and deploying guardrails
- The path forward
- Primary standards and reference frameworks
Defining the guardrail: Why a prompt is not a control
At their core, AI guardrails are the layered technical, procedural, and operational controls that govern what an artificial intelligence system is allowed to ingest, access, execute, and deliver. Many guardrails operate outside the model, checking inputs, retrieved information, proposed actions, and responses. These runtime controls complement model training and behavioral instructions.
To understand what guardrails are, it helps to understand what they are not:
- They are not system prompts: Telling a model in plain English to “be helpful and never disclose company secrets” is a soft behavioral suggestion, not a security perimeter. Under targeted adversarial pressure, language models regularly bypass their own system instructions.
- They are not training-time alignment: Techniques like Reinforcement Learning from Human Feedback (RLHF) establish foundational conversational tendencies during development. But alignment cannot enforce company-specific data retention, dynamic IAM rules, or regional privacy regulations on the fly.
- Content filters are only one component: Filters can block particular words, topics, or sensitive information. Separate authorization controls determine whether an agent may access an Amazon S3 bucket, trigger an external webhook, or read a confidential compensation table.
Guardrails should have defined objectives and be tested and monitored. Some enforce explicit rules; others rely on probabilistic detection and can miss threats or block legitimate requests.
The four architectural layers
One useful way to organize guardrails is across four layers: data, model, application, and infrastructure. Implementations vary, and some controls span multiple layers.
| Layer | Primary operational focus | Representative defense mechanisms |
|---|---|---|
| Data layer | Incoming payloads, context pools, training data, and RAG vector stores | PII masking and tokenization, document-level authorization, input sanitization, and data minimization |
| Model layer | Inference safety, conversational trajectory, and semantic boundaries | Classifier-based HAP (hate, abuse, profanity) detection, prompt interception, and real-time jailbreak scoring |
| Application layer | Business logic, user role identity, and functional schemas | Role-based and attribute-based access controls (RBAC/ABAC), JSON output schema validation, and intent filtering |
| Infrastructure layer | System compute, API endpoints, network traffic, and agent protocols | Model Context Protocol (MCP) server allowlisting, session rate limiting, scoped credentials and token audience validation, and inter-agent isolation |
Data layer
Data guardrails can inspect information before it reaches a model. Depending on their configuration, they may detect credentials, sanitize inputs, and mask or tokenize personally identifiable information (PII) in submitted files or retrieved documents.
Retrieval-augmented generation (RAG) applications retrieve information from external sources to help generate responses. They should apply zero-trust access controls and enforce source-document permissions before passing retrieved content to the model. If an employee cannot access payroll records, retrieval controls should exclude them. Teams should test that these restrictions remain effective when source permissions change.
Model layer
Sitting directly at the input and output boundaries of the model, these controls score prompt semantics and model responses. They evaluate linguistic sequences against safety taxonomies to detect jailbreak attempts, base64 encoding tricks, and indirect prompt manipulation.
If an incoming prompt attempts to trigger an unaligned persona, an interception layer can rewrite or harden the prompt before processing. On the way out, secondary classifiers scan the output to catch abusive language, hallucinations, or toxic phrasing.
Application layer
The application layer bridges natural language and corporate business logic. It evaluates user permissions through Policy-Based Access Control (PBAC) or Role-Based Access Control (RBAC).
While a customer care agent and a legal counsel might use the same foundational LLM, application guardrails constrain what features and schemas each role can invoke. It also validates generated formats, ensuring that if an enterprise workflow expects structured JSON, a rambling conversational paragraph is rejected before breaking an automated backend pipeline.
Infrastructure layer
The computational substrate represents the final technical boundary. Infrastructure controls can combine API rate limits, usage quotas, and spending limits to reduce excessive resource consumption. Authentication and access controls are also needed to address unauthorized use.
In agentic setups, this layer monitors inter-agent communication, restricts network-level egress, and enforces strict server allowlisting for tools using protocols like the Model Context Protocol (MCP). Blocking unauthorized outbound calls requires configured network controls, tool permissions, or sandboxing. MCP alone does not establish those protections.
Anatomy of an execution: The five-stage operational loop
To understand how guardrails work in a live environment, consider a common scenario: a user prompts an AI enterprise assistant to analyze quarterly account performance and execute a scheduled client billing adjustment.
User Request
↓
[Step 1. Classify Request & Evaluate Policy] → (Detect intent, map permissions, check PII)
↓
[Step 2. Constrain Context, Tools & Data] → (Scope RAG retrieval, enforce IAM token)
↓
[ Model Generates Reasoning/Draft Action ]
↓
[Step 3. Validate Action Pre-Execution] → (Check tool authorization, trigger human sign-off)
↓
[Step 4. Inspect Output & Mutated State] → (Verify schema, check grounding, mask secrets)
↓
[Step 5. Escalate, Log & Incident Feedback] → (Immutable audit trail, telemetry for tuning)
- Classify the request and policy: The request is analyzed on arrival. The input is checked for prompt injections, the user’s role is authenticated, and the intent is categorized.
- Constrain context, tools, and data: The system defines the execution sandbox. The model is supplied strictly with retrieval chunks the user is cleared to read. Unrelated plugins and APIs are locked away.
- Validate proposed actions before execution: The model reasons through the task and proposes calling a database function to update billing. Before the API call executes, the guardrail checks parameters against strict business policies. If the financial threshold exceeds automated limits, execution halts and routes to a human supervisor for sign-off.
- Inspect outputs and changed state: Once allowed actions finish, the resulting output is scanned. The guardrail checks that no customer credit card numbers or account secrets are leaked in the text, validates that facts align with reference data, and ensures the response adheres to formatting specifications.
- Escalate, log, and improve: Record policy decisions, tool calls, approvals, and outcomes in access-controlled, tamper-resistant logs. Redact secrets, limit personal-data retention, and use incident findings to improve controls.
More must-read AI coverage
- SS&C Intralinks DealCentre AI vs. Datasite: Which platform is built for the future of dealmaking?
- SS&C Intralinks FundCentre AI vs. Juniper Square: Which platform better supports modern private markets fund managers?
- Why Data, Not Models, Determines AI Success
- The Rise of the AI-Native Factory: How Physical AI Is Transforming Manufacturing
The rising stakes: Agents, tool hijacking, and emergent exploits
Traditional cybersecurity defended structured code against predictable vulnerabilities. Generative AI inverts this model: systems now parse untrusted, highly ambiguous natural language inputs with access to live internal tools and data.
IBM’s 2025 Cost of a Data Breach Report put the average U.S. breach cost at $10.22 million. Among organizations in the study that reported a breach of an AI model or application, 97% reported lacking proper AI access controls.
Leaving AI agents ungoverned opens the door to severe exploitation vectors:
- Indirect prompt injection: Adversaries do not need direct access to a prompt box. By planting hidden, malicious instructions inside an email, a public document, or a shared workspace channel, an attacker can hijack an AI assistant that ingests that data during search or RAG summarization. A 2024 vulnerability analyzed by PromptArmor demonstrated that an attacker could plant instructions in a public channel to force an AI assistant into exfiltrating private API keys through innocent-looking markdown links.
- Chained vulnerabilities: In June 2026, Varonis disclosed SearchLeak, a vulnerability chain in Microsoft 365 Copilot Enterprise Search tracked as CVE-2026-42824. Researchers combined parameter-to-prompt injection, an HTML rendering race condition, and server-side request forgery to demonstrate data theft after a victim clicked a crafted link. Microsoft remediated the vulnerability.
- Model context protocol (MCP) exploitation: Giving models dynamic access to third-party MCP servers creates a significant tool-escalation surface. Malicious tool descriptions can influence an agent when an application includes them in the model’s context. Teams should treat third-party tool metadata as untrusted input and review integrations before granting access.
- Shadow AI and corporate blind spots: Workers routinely copy confidential balance sheets, client contracts, and strategic decks into consumer-grade chatbots to accelerate daily tasks. Cyberhaven’s 2026 enterprise study found that 39.7% of the AI interactions it analyzed involved sensitive data, including prompts, copying and pasting, and file uploads. IBM found that organizations with high levels of shadow AI had average breach costs $670,000 higher than organizations with low or no shadow AI.
The strategic cost of getting guardrails wrong
Building guardrails requires balancing systemic friction with operational safety. Miscalibrating this balance introduces serious organizational friction without explicitly using trade-off models:
- False positives and workflow stoppages: When content and regex filters are configured too aggressively, they flag ordinary business language. A finance employee querying legitimate accounts or a developer debugging code with unusual syntax gets repeatedly blocked, generating alert fatigue and killing team velocity.
- The shadow bypass reaction: When guardrails become overly restrictive or introduce jarring latencies, employees do not abandon AI. They bypass enterprise firewalls entirely, routing sensitive workflows through personal smartphones, consumer web apps, and unmonitored home devices.
- Performance overhead and latency: Running sequential evaluations, inspecting prompts, evaluating vector chunks, calling external classifier models, and scanning output tokens adds measurable computational overhead. The added latency varies by implementation, so teams should measure response times under realistic production loads.
- The false sense of security: The most insidious risk is psychological. When organizations install an off-the-shelf content filter, leadership often mistakenly assumes the entire agentic pipeline is hardened. Teams loosen their manual oversight, only for a subtle semantic prompt injection to bypass the filter and execute an unmonitored workflow.
Why agent permissions matter
An AI agent’s access should be limited to the data and tools needed for its task. A workflow that summarizes supplier documents may need read access, while one that updates supplier records also needs narrowly defined write permissions.
If an agent uses a broadly privileged account, a successful prompt injection may misuse the tools and permissions available to it. Restricting access reduces the potential damage, even when a malicious instruction bypasses a content check.
User-initiated workflows should preserve the initiating user’s authorization limits. Background workflows may require a separate, narrowly scoped service identity. Each receiving service should validate credentials intended for that service; forwarding the same user token indiscriminately across tools and agents can introduce security risks.
Permissions alone are not enough. Before an agent changes billing details, sends sensitive information, or performs another consequential action, the application should validate the proposed action against business rules and require approval where appropriate. IT teams should also be able to revoke access and stop the workflow.
Business, technology, and consumer realities
The deployment of AI guardrails carries far-reaching consequences across every sector of modern industry.
Business and governance
Grant Thornton’s 2026 AI Impact Survey found that 78% of business executives lacked strong confidence that they could pass an independent AI governance audit within 90 days. Separately, Deloitte’s 2026 report found that around 60% of workers had access to sanctioned AI tools. Deloitte also reported that only 21% of companies planning to deploy agentic AI within two years had a mature model for agent governance.
A 2024 California Management Review article cited research suggesting that companies implementing generative AI with appropriate guardrails may be 27% more likely to achieve higher revenue performance than peers without them. The finding does not establish that guardrails alone caused the difference.
Technology and infrastructure
Development patterns are fundamentally restructuring. Teams can use runtime middleware to manage policies separately from application code. This approach can make controls easier to update and test, although implementation requirements vary.
In advanced architectures, brand guidelines, forbidden operational boundaries, and escalation protocols are managed like structured content, version-controlled, tested against continuous evaluation suites, and hot-swapped without recompiling underlying code bases or fine-tuning model weights.
Consumer and societal trust
For consumers, guardrails represent the thin line separating helpful automation from systemic discrimination and digital deception. When enterprise bots handle apartment lease approvals, triage medical inquiries, or set consumer credit thresholds, unmonitored bias directly impacts human livelihoods.
Guardrails can support transparency, bias monitoring, and human review when those controls are explicitly implemented. They do not guarantee fair outcomes or effective oversight.
Blueprint for decision-makers: Evaluating and deploying guardrails
For engineering leaders and enterprise buyers navigating an overcrowded software ecosystem, separating enterprise-grade guardrails from marketing fluff comes down to seven foundational questions:
- What specific bottleneck are you solving? Are you preventing conversational hallucinations, enforcing role-based data access across RAG documents, or blocking unauthorized API calls from an autonomous bot?
- Where does enforcement live? Does the system rely on fragile system prompt instructions, or does it enforce deterministic policies outside the model at the API gateway and identity layers?
- How does the system handle identity? Does each data source and tool enforce permissions appropriate to the user, agent, and task? Are credentials scoped to the receiving service, and can access be revoked?
- Can the system stop an autonomous workflow? Are there task-specific limits on iterations, execution time, spending, and tool calls? Which actions require human approval before execution?
- How is the policy maintained? Can legal, compliance, and product teams update safety boundaries and voice rules via version-controlled dashboards, or does every change require engineering pull requests and model redeployments?
- What is the operational latency tax? What are the measurable performance costs (in milliseconds and compute) across the 95th and 99th percentiles of production traffic?
- What is the recovery protocol when an exploit breaks through? Can the platform abstain from answering, fall back to a simpler deterministic engine, revoke session tokens, and trigger a human incident alert in real time?
The path forward
The fundamental measure of an enterprise AI deployment is not how well it performs during a scripted product demonstration. It is how safely and predictably it behaves when hit with an adversarial prompt, a malformed database payload, or an edge-case transaction in live production.
Treating AI guardrails as a decorative filter bolted onto the end of a project is a recipe for operational failure. Organizations that succeed in the autonomous era will be those that treat guardrails as core infrastructure: architected across data and identity, enforced at runtime, governed by clear ownership, and monitored continuously as a living system.
Primary standards and reference frameworks
- NIST AI Risk Management Framework and Generative AI Profile: AI RMF 1.0 provides a framework for managing AI risks. NIST AI 600-1 is a separate companion profile addressing generative AI risks.
- OWASP Top 10 for LLM Applications: Security guidance covering risks including prompt injection, sensitive information disclosure, improper output handling, and excessive agency.
- ISO/IEC 42001: An international standard specifying requirements for establishing, maintaining, and continually improving an AI management system.
- C2PA Specifications: Specifications for recording and verifying the provenance of digital content; provenance does not establish that the content is factually true.
- NIST Privacy Framework: A voluntary framework for identifying and managing privacy risks.
Want to learn more AI tips, tricks, and prompting techniques? TechRepublic readers get free 7-day access to The Neuron Academy, our practical learning platform designed to help professionals use AI more confidently at work. Browse all lessons →
Let us teach you How to Talk to AI for free! Try our six-minute course at The Neuron Academy and learn a few simple ways to write better prompts and get more useful results from AI, or browse our other AI course for free for seven days. Check out all the lessons here →