


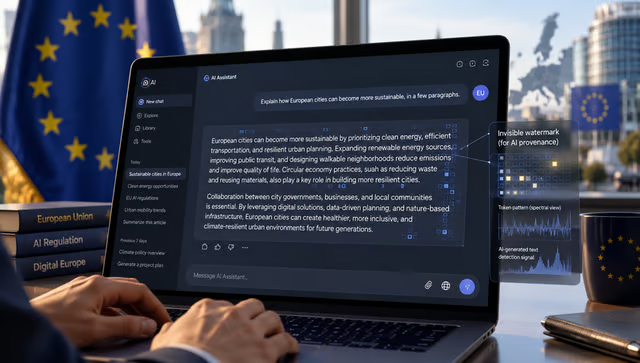
ChatGPT responses in Europe may soon carry a signal users cannot see.
OpenAI is rolling out invisible text watermarks for eligible ChatGPT and Codex output in the European Union across all plans. The provenance system is designed to help identify AI-generated text as transparency requirements under the EU AI Act take effect.
Users will not need to enable anything themselves, but the watermark will not apply equally to every response — and editing, translation or paraphrasing can significantly weaken detection.
How OpenAI’s invisible watermark works
OpenAI calls its technology textGrain. The system slightly changes how its models choose among possible next words or word pieces. Across a long enough passage, those choices create a statistical pattern that compatible detection software can recognize.
No hidden characters, extra spaces, or unusual punctuation need to be inserted. Copying a response into another document therefore does not automatically strip the watermark because the wording itself carries the detectable pattern. EU provenance rules form part of the EU AI Act, which sets transparency obligations for providers of general-purpose AI systems.
Code gets different treatment. Fewer acceptable choices may exist for the next piece of code, limiting how much textGrain can alter model output without affecting correctness.
EU guidance also excludes code snippets and responses below 200 tokens, roughly 150 English words, from text-watermarking expectations. Codex is included in the rollout, but its inclusion does not mean every generated code snippet will contain a detectable watermark.
Detection varies with length and editing
Longer passages give the detector more material to examine. Testing produced the following results across several evaluations.
| Test | Reported detection rate |
| 200-token passage at a 1% false-positive rate | About 80% |
| 400-token passage at a 1% false-positive rate | About 95% |
| 400-token passage after 10% of words were replaced with synonyms | About 66% |
| 400-token passage after 25% of words were replaced | 17% |
Editing can weaken the pattern considerably, and translation or substantial paraphrasing can also interfere with detection. Highly constrained material such as mathematics produced lower rates because the model has fewer acceptable wording choices.
A match does not identify a user, reveal the original prompt or prove authorship. A negative result is also inconclusive because editing, paraphrasing or translation can weaken or remove the detectable signal.
Similar debates around AI-generated content provenance have grown as technology companies experiment with machine-readable markers.
Detector access will initially be limited to approved researchers and qualified expert organizations. Ordinary ChatGPT users will not receive a public detector as part of the launch.
More must-read AI coverage
- SS&C Intralinks DealCentre AI vs. Datasite: Which platform is built for the future of dealmaking?
- SS&C Intralinks FundCentre AI vs. Juniper Square: Which platform better supports modern private markets fund managers?
- Why Data, Not Models, Determines AI Success
- The Rise of the AI-Native Factory: How Physical AI Is Transforming Manufacturing
ChatGPT users in the EU should keep a disclosure trail
Anyone using ChatGPT for work governed by an AI disclosure policy should continue following that policy after watermarking starts. An invisible marker cannot document why AI was used, how a draft changed afterward, or whether its use complied with an employer, publisher, client, or school rule.
Users and organizations can take a few additional steps.
- Keep your own record of AI use. Version history can preserve changes made after a ChatGPT draft, and a short note documenting permitted AI assistance can provide context if a finished document is questioned.
- Avoid treating a detector match as proof of authorship. A positive result can justify reviewing how AI was used, but it should not settle an authorship dispute on its own. Organizations using automated checks should define how results fit into their AI governance policies before relying on them in employment, academic, or publishing decisions.
EU users may never have direct access to OpenAI’s detector, which makes their own records more important when AI use needs to be explained later.
OpenAI’s watermark may give researchers and organizations another way to identify AI-generated text, but for users, it is still only a provenance signal. When AI use needs to be explained or disclosed, ordinary documentation remains more reliable than an invisible marker.
Learn a few simple ways to get more useful answers from AI with our free six-minute How to Talk to AI course. The Neuron Academy also offers seven days of free access to its other AI courses. Check out all the lessons here →