


Intel is expanding its open infrastructure approach to help enterprises scale agentic AI workloads.
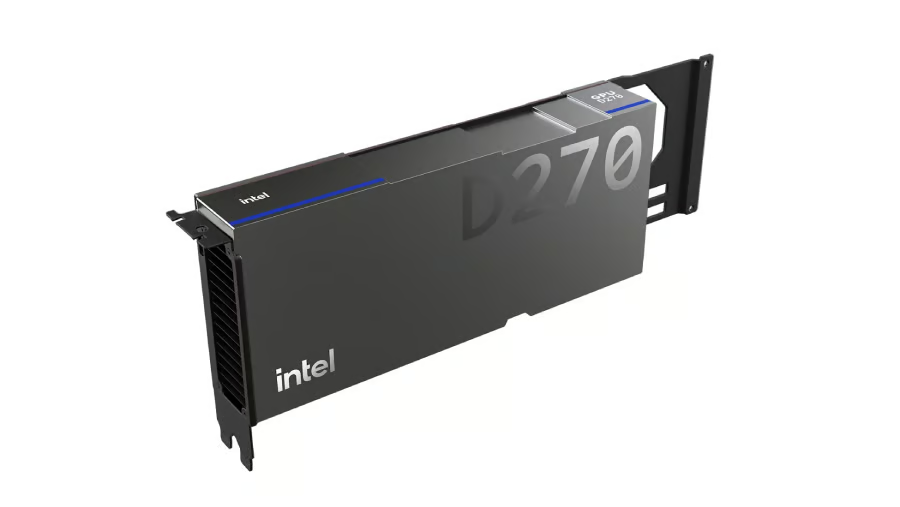
At the 2026 Open Compute Project (OCP) Global Summit, Intel showcased Xeon-based rack designs developed with ecosystem partners and shared new technical details about its Intel GPU D-series. The company aims to make AI infrastructure more economical through CPUs, accelerators and interoperable software.
For IT teams scaling agentic AI, the practical question is whether these options can meet performance requirements within existing power, cooling and software budgets.
Kevork Kechichian, Intel’s executive vice president and general manager of its Data Center Group, said success in agentic AI will depend on open, heterogeneous infrastructure. He added: “Intel is helping customers build on their existing investments while creating a flexible foundation to scale emerging AI workloads efficiently.”
Intel says customer sampling of the GPU D-series is underway. The announcement does not specify general availability dates for the GPU or individual Xeon rack solutions.
How Intel’s solution will work
Intel’s announcements cover Xeon-based rack designs and its inference-focused GPU D-series, rather than one specified system combining both.
The company says select Xeon 6+ configurations exceed 46,000 CPU cores per rack at 133.45 kW of total rack power. These are rack-level figures, not specifications for an individual processor.
For the GPU D-series, Intel lists up to 480 GB of LPDDR5X memory, 1.5 TB/s of memory bandwidth and 1.3 petaflops of FP8 compute. Intel’s own PCIe card has 160 GB of memory; partner-built cards can offer configurations up to 480 GB. Intel positions the GPU for sustained, memory-intensive inference workloads.
Intel says many of the showcased Xeon rack designs use OCP’s Open Rack v3 (ORv3) standard. This supports interoperability within compatible open rack infrastructure, but buyers should still verify rack, power and cooling requirements before planning deployment.
The announcement does not provide comparative benchmarks for complete agentic AI workflows. Businesses should request workload-specific testing before treating the hardware specifications as evidence of deployment performance or savings.
What's hot at TechRepublic
- Blackpoint Cyber vs. Arctic Wolf: Which MDR Solution is Right for You?
- Why AWS Sellers Choose Deepgram Over Other Voice AI Tools
- SS&C Intralinks DealCentre AI vs. Datasite: Which platform is built for the future of dealmaking?
- SS&C Intralinks FundCentre AI vs. Juniper Square: Which platform better supports modern private markets fund managers?
- Verito vs. Rightworks: Which IT Provider Is Best for Your Firm?
What this means for enterprises
Intel’s approach gives IT teams additional infrastructure options to evaluate, but open standards alone do not establish lower costs or eliminate vendor dependencies. Buyers should assess supported frameworks, drivers, management tools and the effort required to move applications between platforms.
Facility readiness should be part of that evaluation. For any proposed configuration, confirm whether the existing data center can provide the required power and cooling, and include necessary upgrades in the deployment budget.
Performance testing should reflect actual business use: the models being served, context lengths, concurrent users and acceptable response times. Measure the complete workflow, including retrieval and tool execution, rather than relying only on core counts or peak compute figures.
Finally, compare total costs, including hardware, memory costs, energy, software integration and support. Before committing, ask the supplier to confirm the exact configuration, delivery schedule and performance under representative workloads.
Read more: As AI racks grow denser, power, cooling and hardware management are becoming central to deployment planning.